Hugging Face's logo Hugging Face
  • Models
  • Datasets
  • Spaces
  • Buckets
  • Docs
  • Enterprise
  • Pricing
    • Website
      • Tasks
      • HuggingChat
      • Collections
      • Languages
      • Organizations
    • Community
      • Blog
      • Posts
      • Daily Papers
      • Hardware
      • Learn
      • Discord
      • Forum
      • GitHub
    • Solutions
      • Team & Enterprise
      • Hugging Face PRO
      • Enterprise Support
      • Inference Providers
      • Inference Endpoints
      • Storage Buckets

  • Log In
  • Sign Up

Vision, Language and Reading

non-profit
https://www.vlr.ai/
VLR-CVC
Activity Feed

AI & ML interests

Multimodal AI, Document Understanding, Reading Systems.
Recent Activity

mserrao  authored a paper 1 day ago
CoSMo: A Multimodal Transformer for Page Stream Segmentation in Comic Books
mserrao  authored a paper 1 day ago
Linear-Time Context Compression with State-Space Encoding
mserrao  authored a paper 1 day ago
ICDAR2026 Competition on Multimodal Reasoning over Documents in Multiple Domains
View all activity

Papers

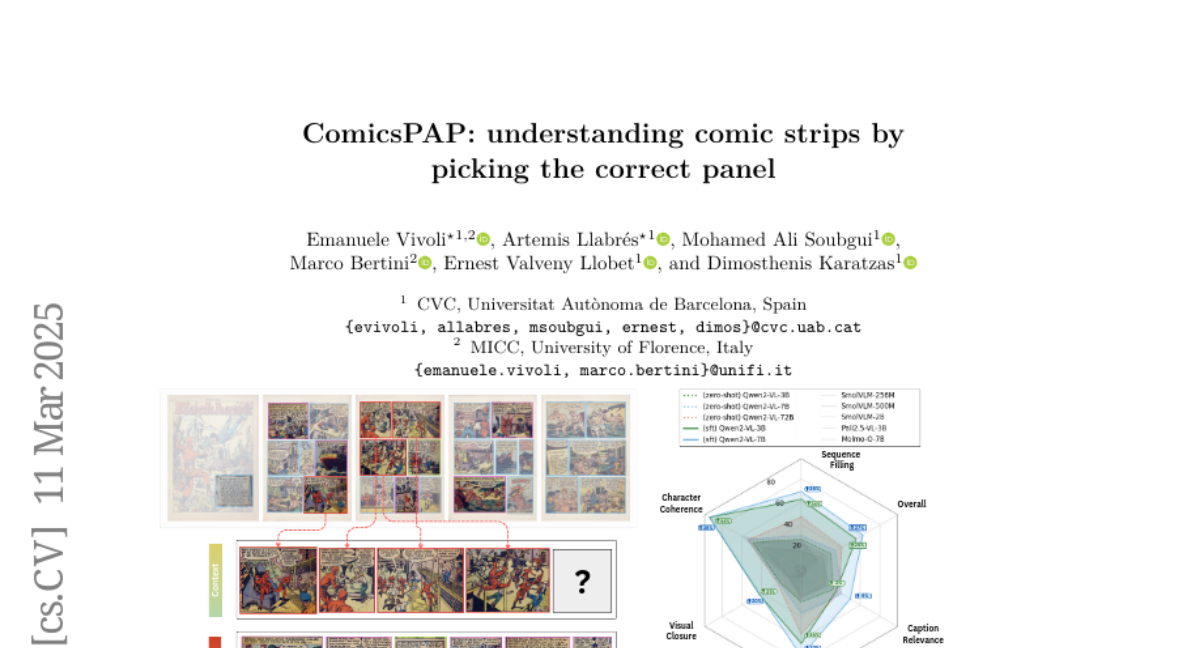
ComicsPAP: understanding comic strips by picking the correct panel
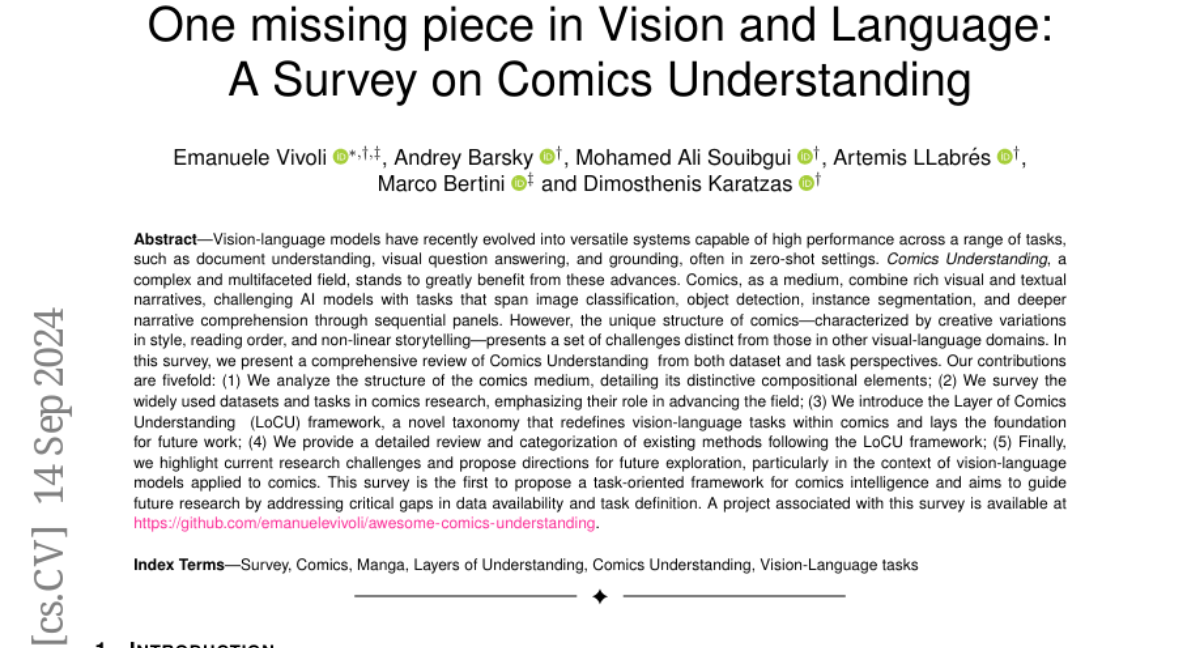
One missing piece in Vision and Language: A Survey on Comics Understanding

View all Papers

Artemis Llabrés's profile picture Emanuele Vivoli's profile picture Mohamed Ali Souibgui's profile picture Khanh Nguyen's profile picture Dimosthenis Karatzas's profile picture Eric López's profile picture Tomás Ockier Poblet's profile picture Serra's profile picture Amritpal Singh's profile picture Samuel Ortega Cuadra's profile picture Christos Georgakilas's profile picture

VLR-CVC 's datasets 2

VLR-CVC/DocVQA-2026

Viewer • Updated Sep 8 • 73 • 1.01k • 74

VLR-CVC/ComicsPAP

Viewer • Updated Sep 29, 2025 • 80.6k • 3.01k • 16
Company
TOS Privacy About Careers
Website
Models Datasets Spaces Pricing Docs